Posted by: Matt Lewis
Published:
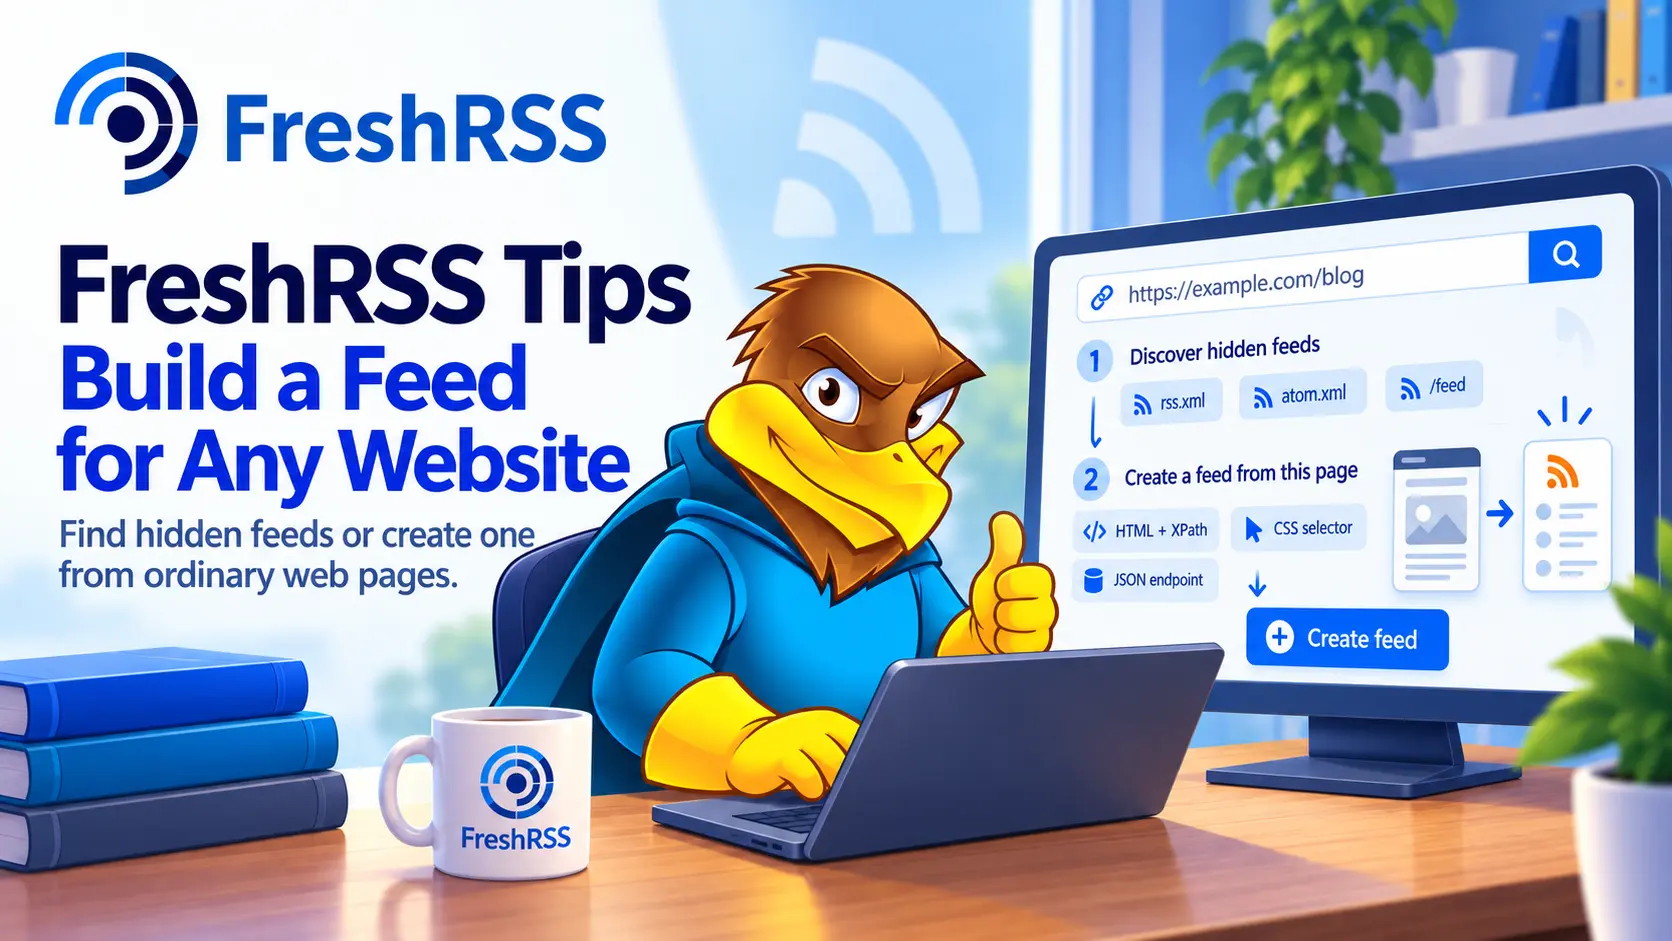
Running a feed reader creates a very specific annoyance: you find a site you want to follow, look for the little orange icon, and come up empty. Now you are supposed to remember to check the page yourself, which means you probably will not.
Some of the sites you gave up on already publish a feed and simply do not advertise it. For the rest, FreshRSS can build one from the page itself.
Even though browsers no longer make feeds easy to spot, a lot of sites still publish one without linking to it prominently.
Three things to try, in order.
Paste the homepage URL into FreshRSS. FreshRSS reads the page and looks for a feed declaration for you. Most CMS platforms add one automatically, so this often solves the problem immediately.
Look at the page source yourself. View source and search for rss+xml or atom+xml. You are looking for something like:
<link rel="alternate" type="application/rss+xml" title="Feed" href="/feed.xml">Guess. Feed URLs are usually predictable. Try these against the site’s root:
That last one is the WordPress fallback and it works even when pretty permalinks are disabled.
Before building a scraper, try the known endpoints below. These platforms expose feeds even though the links can be hard to find in their interfaces.
Code and software:
https://github.com/OWNER/REPO/releases.atomhttps://github.com/OWNER/REPO/tags.atomhttps://github.com/OWNER/REPO/commits.atomhttps://pypi.org/rss/project/PACKAGE/releases.xmlPeople and communities:
https://INSTANCE/@USERNAME.rsshttps://www.reddit.com/r/SUBREDDIT/.rsshttps://stackoverflow.com/feeds/tag/TAGNAMEhttps://www.youtube.com/feeds/videos.xml?channel_id=UC...WordPress:
https://SITE/category/NAME/feed/https://SITE/tag/NAME/feed/https://SITE/comments/feed/https://SITE/?s=TERM&feed=rss2For GitHub, subscribe to releases if you want shipped versions. The commits feed is useful when you want to follow development, but it can be much busier. Tags are useful for projects that mark versions without publishing GitHub Releases.
The YouTube URL needs the channel’s UC... ID, not its @handle. If you have only the channel page, the YouTubeChannel2RssFeed extension can convert its URL for you. If the resulting feed goes quiet, open that feed URL in a browser before troubleshooting FreshRSS.
Reddit may rate-limit its feeds. If one errors intermittently, try a longer refresh interval.
FreshRSS can turn an ordinary HTML page into a feed.
When you add a feed in FreshRSS, the Type of feed source dropdown starts with normal RSS or Atom. It also offers several ways to turn HTML or JSON into a feed:
Pick HTML + XPath, and the form expands into a set of XPath expression fields. You are telling FreshRSS three things: where the items are on the page, and then, within each item, where the title and the link are. Everything else is optional.
Suppose the page uses a repeated list of <article> elements like this:
<div class="post-list">
  <article class="post featured">
    <h2 class="post-title"><a href="/news/thing-happened/">A Thing Happened</a></h2>
    <time datetime="2026-09-21T09:00:00Z">21 September</time>
    <p class="excerpt">Short summary of the thing.</p>
    <img class="thumb" src="/img/thing.jpg" alt="">
  </article>
  ...
</div>The configuration for that page:
| Field | XPath expression |
|---|---|
| Feed title | "Example News" |
| Item (most important) | //article[contains(@class, "post")] |
| Item title | descendant::h2 |
| Item URI | descendant::a/@href |
| Item content | descendant::p[@class="excerpt"] |
| Item date | descendant::time/@datetime |
| Item thumbnail | descendant::img/@src |
Three details are worth explaining.
contains(@class, "post") rather than @class="post". The element in the example has class="post featured". An exact match would find nothing. Class attributes almost always carry more than one value, so contains() is nearly always what you want.
descendant:: everywhere below the item. Once you have selected the item, every other expression is evaluated relative to it. descendant::h2 means “an h2 inside this item.” Starting one of those with // would search the whole document again and give every item the same title.
A quoted string as the feed title. XPath expressions that return a string work anywhere, so "Example News" is a valid feed title, and "Anonymous" is a valid item author. Handy when the page has no sensible element to point at.
Firefox and Chrome will both hand you an XPath: right-click an element in the inspector, then Copy → XPath.
Then throw most of it away.
The browser gives you an absolute path such as /html/body/div[3]/div[2]/main/article[1]. It is tied to the current layout and may break as soon as the site adds a wrapper element. Use it to understand the structure, then rewrite it as a relative expression anchored to a stable class name, ID, or semantic tag.
In Add feed → HTML + XPath → Item, replace the browser-generated path with a shorter expression anchored to the page structure:
The shorter version still breaks if the site renames the class, but ordinary layout changes are less likely to affect it.
Scraping fails in a small number of predictable ways.
Every article has the same title. Your title expression starts with // instead of descendant::, so it is matching the whole document rather than the item.
You get one item, not many. Your item expression is probably too specific. Look for an index such as article[1] or an ID that only appears once.
Links come out broken or relative. FreshRSS resolves relative links against the source page, but pages with odd <base> tags or with links inside thumbnails can confuse it. If you hit this, build the URL explicitly: concat("https://example.com", descendant::a/@href).
Nothing at all comes back. This is usually JavaScript. See below.
Before you write a dozen XPath expressions against someone’s markup, check whether the page hands you structured data for free.
Many news sites and blogs embed structured data for search engines in a <script type="application/ld+json"> block. Because that data is intended for machines, it often changes less frequently than the surrounding layout.
FreshRSS has a feed type for exactly this: HTML + XPath + JSON dot notation. You give it an XPath expression to pull the JSON out of the page, then dotted paths to walk the JSON.
Choose Add feed → HTML + XPath + JSON dot notation. If the page’s JSON-LD is an ItemList whose itemListElement entries contain an item object, the fields could look like this:
| Field | Value |
|---|---|
| XPath for JSON in HTML | //script[@type="application/ld+json"] |
| Item | itemListElement |
| Item title | item.headline |
| Item URI | item.url |
| Item date | item.datePublished |
Check the JSON on the target site first. Some pages describe only the current article, which will not give you a useful feed. When a page does expose a list, the mapping can survive layout changes that would break an HTML scraper.
If the page loads its content with JavaScript, open the network tab and watch what it fetches. Very often there is a plain JSON endpoint behind it. Point the JSON (Dotted paths) feed type at that URL directly and you get a stable feed with no scraping at all.
Dotted paths use dots and numeric brackets, such as data.items and meta.links[0]. They also support string concatenation with &, so meta.title & ": Example" is valid.
Plenty of sites publish only a paragraph and a “read more” link in their feeds. FreshRSS can fetch the article page and pull in the full body.
In Feed settings → Advanced → Article CSS selector on original website, enter a selector for the article body, such as #article .content. FreshRSS then fetches each article page and pulls that section into the entry. Start with an ID when the page has a useful one, and separate multiple selectors with commas if the body spans several blocks.
The CSS selector of the elements to remove field below it strips things you do not want in the extracted article, such as a newsletter signup or related-articles rail. A starting value is footer, aside, .newsletter-signup, .related-posts, .social-share, [data-ad]. Check a few results before adding more selectors.
Conditions keep FreshRSS from fetching article pages you do not plan to read.
The Conditions for content retrieval field accepts the search syntax covered in part one. Full-text extraction then runs only for matching articles.
So instead of fetching every article on a busy feed, you fetch only the ones you would actually read.
For example, Feed settings → Advanced → Conditions for content retrieval could contain any of these:
If a feed publishes fifty items a day and only five match, FreshRSS makes five article-page requests instead of fifty.
If you would rather not write CSS selectors for each site, two extensions apply the same general approach as a browser’s reader mode.
Af_Readability and Readable both do this. They are less precise than a hand-written selector and make the same number of outbound requests, but they avoid per-site configuration. That is useful when you follow many sites only occasionally.
The two features can work together. XPath scraping discovers items from a listing page, then CSS full-text extraction runs against each item’s URL:
The result is a full-text feed for a site that never published one.
For this to work, the item URI has to resolve to the actual article page. FreshRSS can resolve ordinary relative links, but test a few entries before you trust the scraper.
Then set the CSS selectors in the same feed’s Advanced settings. On a busy site, use conditions to limit how many article pages FreshRSS fetches.
A proper RSS feed gives every item a stable unique identifier, which is how FreshRSS knows it has seen an article before. A scraped web page gives you nothing of the kind, so FreshRSS has to work it out.
Two controls handle this.
Item unique ID in the XPath configuration can point to a stable identifier on the page, such as an article ID attribute or a permalink slug. If you leave it empty, FreshRSS computes a hash instead.
Article unicity criteria in the feed’s Advanced settings picks what that hash is computed from. The options run from Standard ID through Link, Title, Content, and various combinations like Link + Date + Title.
The symptom of getting this wrong is duplicates: the same article appearing repeatedly, usually every time the page changes in some cosmetic way. If that happens, move to a criterion based on the link alone, which is generally the most stable thing on a scraped page.
An XPath scraper configuration might represent an hour of work. FreshRSS’s normal OPML export saves the feed list without XPath expressions, CSS selectors, credentials, or refresh intervals. For a complete backup, use a database backup or portable SQLite export.
FreshRSS can import extended OPML containing scraper settings. That makes it useful for building or sharing a scraper definition by hand. This example follows FreshRSS’s OPML extension format; it is not what the regular export produces:
<outline xmlns:frss="https://freshrss.org/opml"
text="Example News"
type="HTML+XPath"
xmlUrl="https://www.example.net/news/"
htmlUrl="https://www.example.net/news/"
frss:priority="main"
frss:ttl="10800"
frss:xPathItem="//article[contains(@class, 'post')]"
frss:xPathItemTitle="descendant::h2"
frss:xPathItemUri="descendant::a[string-length(@href)>0]/@href"
frss:xPathItemContent="."
frss:xPathItemTimestamp="descendant::time/@datetime"
frss:xPathItemThumbnail="descendant::img/@src"
frss:cssFullContent="article .body"
frss:cssContentFilter=".newsletter, .related"
frss:filtersActionRead="intitle:sponsored"
/>You can edit a file like this and import it through FreshRSS. Keep the SQLite or database backup as your restore point.
If you get a scraper working for a popular site, share its extended OPML definition. It might save someone else an hour of arguing with XPath. The FreshRSS scraping documentation links to a community-maintained collection of importable OPML files with XPath settings for various websites.
The Advanced section handles redirects, cookies, and custom headers.
Not every site responds properly to a default HTTP request. FreshRSS provides these per-feed controls:
Authorization: Bearer ... header for a private feedA scraper depends on markup you do not control. A site redesign can break an XPath expression silently: the feed stops producing items without reporting an error.
Three habits that catch it:
Check the idle feeds report. Subscription management has a statistics view that lists idle feeds. A scraped feed that has produced nothing in three weeks is the first thing to look at.
Keep the definitions somewhere inspectable. If you wrote an extended OPML file, save it. A database or SQLite export preserves the configured feed too. When a scraper breaks, you want the old expressions in front of you while you write the new ones.
Prefer semantic anchors. //main//article[contains(@class, "post")] survives a lot more redesigns than /html/body/div[3]/div[2]/article[1]. Every bit of specificity you can drop is a redesign you might survive.
robots.txt, use a considerate refresh interval, and stop if the site asks you to. If you plan to republish the content rather than read it privately, get permission from the publisher.The page has no stable unique identifier for FreshRSS to use, so it is computing one from content that keeps changing. Common culprits include a view counter, a relative timestamp, or an ad slot.
Fix it either by setting the Item unique ID XPath to a stable value on the page, or by changing Article unicity criteria in the feed’s Advanced settings to something link-based. Check the next refresh; changing the criterion can itself produce duplicates.
Sometimes. If the site uses HTTP basic auth, the username and password fields will handle it. If it uses a token, you can pass an Authorization header. If it needs a session cookie, the cookie option plus a manually supplied cookie string can work.
If it needs a real interactive login with JavaScript, no. That is outside what FreshRSS does.
Start with an interval of three to six hours. A normal feed refresh is one HTTP request, while a scrape with full-text extraction may require dozens.
For a site that publishes a few times a week, every three or six hours is plenty. Set it per feed with Do not automatically refresh more often than in the feed’s Archiving section.
They solve overlapping problems from different directions. RSS-Bridge maintains hand-written adapters for popular sites. If your target is already covered, use the maintained adapter instead of writing and maintaining your own scraper.
FreshRSS’s built-in scraper works with ordinary server-rendered pages, including obscure sites without an RSS-Bridge adapter. There is also an RSS-Bridge extension for FreshRSS if you want both.
There is no global switch. FreshRSS configures extraction per feed because enabling it everywhere would multiply outbound requests by the number of articles received.
If you want something close to it without the per-site configuration work, the Af_Readability or Readable extensions apply a readability algorithm to the feeds you select. The request cost is the same, so choose the feeds carefully either way.
 Shared Web HostingSimple, secure, and reliable cloud hosting
 Semi-Dedicated Cloud HostingHigher power & more resources
 Reseller Cloud Web HostingWhite label & fully customizable

 Contact Support